Organizations are deploying artificial intelligence (AI) faster than they are auditing it. An IBM survey of 2,000 CIOs and CTOs found that 77% say AI adoption is already outpacing their internal governance capabilities.¹ Generative AI now screens and ranks candidates in hiring pipelines, powers customer-facing products, and informs underwriting and revenue operations, often without a systematic review of what those systems learned, from whom, and at whose expense.
AI bias is not primarily a diversity, equity, and inclusion (DEI) compliance issue. It is a data integrity problem, and it is already producing measurable business consequences.
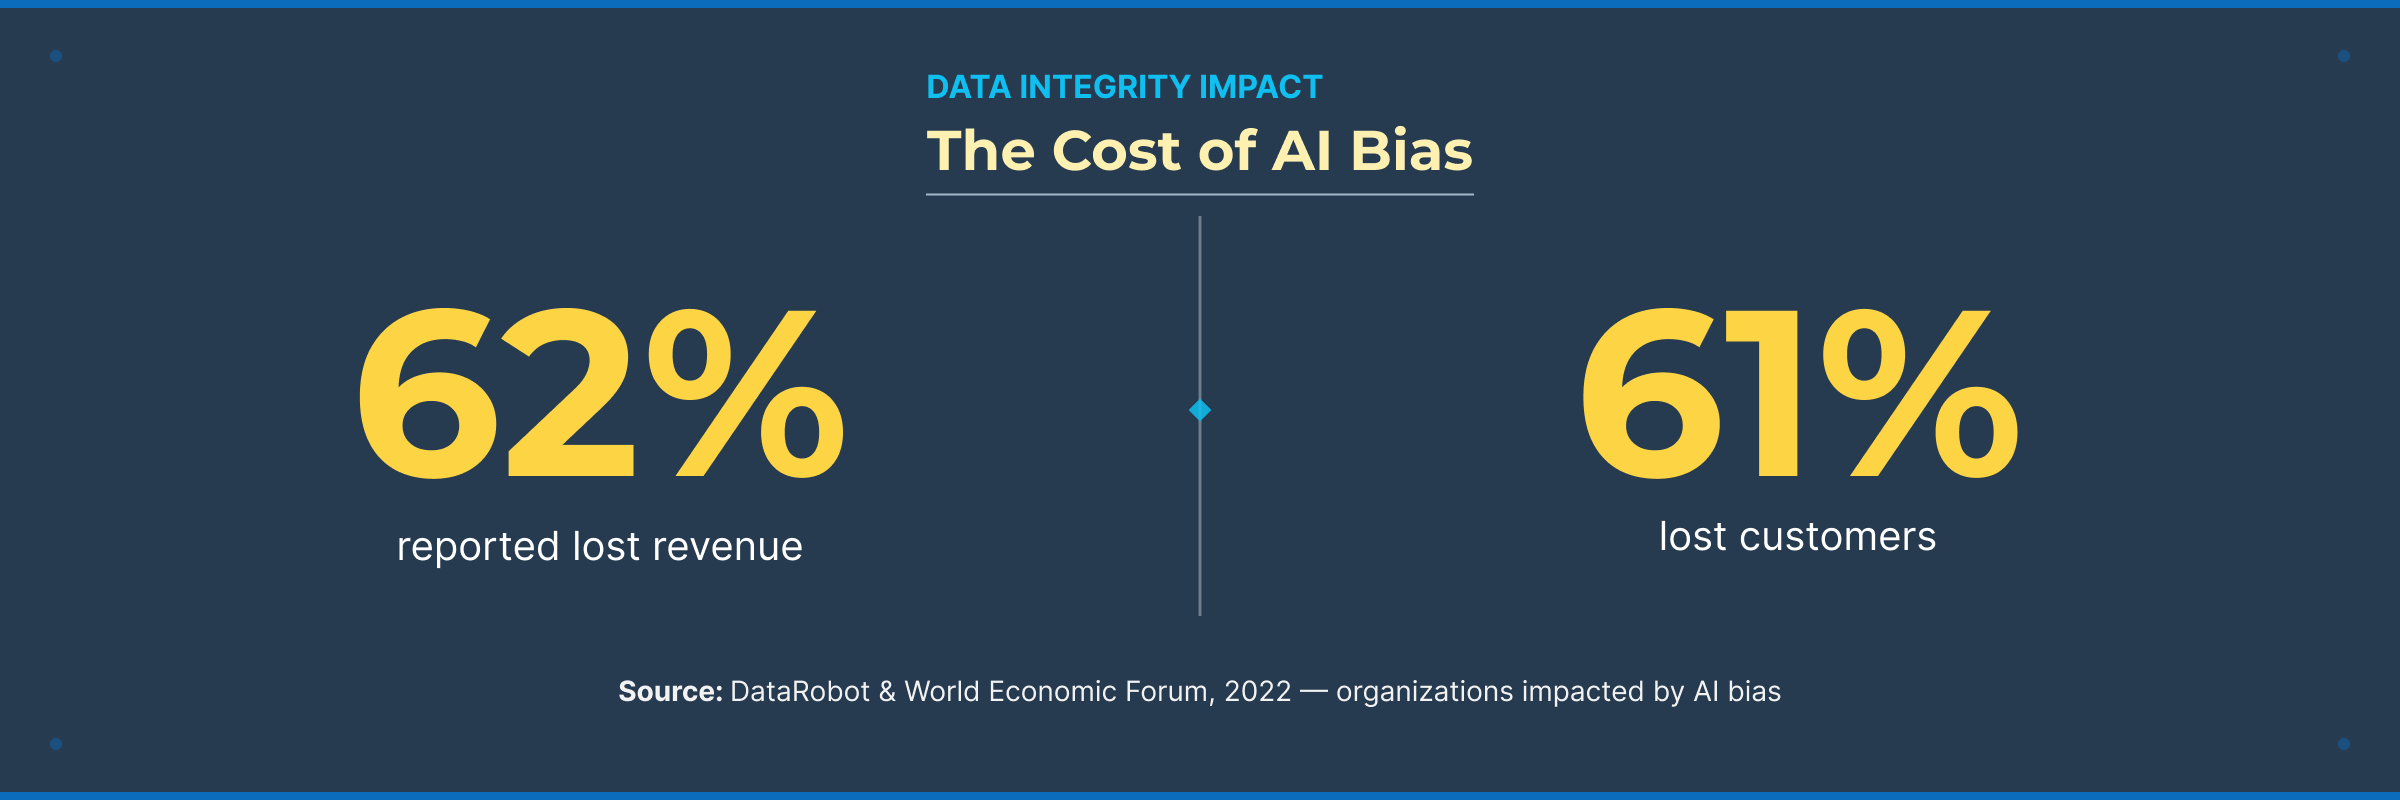
A 2022 DataRobot report, conducted in collaboration with the World Economic Forum, found that of organizations that experienced AI bias, 62% reported lost revenue and 61% lost customers.2
When Gender Shades, the landmark research by computer scientists Joy Buolamwini and Timnit Gebru, revealed that Microsoft's gender classifier erred on 20.8% of darker-skinned women against effectively zero lighter-skinned men, that was more than an ethics failure in isolation.3 It was a product defect that created legal exposure, brand damage, and customer harm simultaneously. That distinction is operational. It determines where accountability lives and what the fix requires.
"AI bias is not primarily a diversity, equity, and inclusion (DEI) compliance issue. It is a data integrity problem, and it is already producing measurable business consequences."
AI delivers genuine operational leverage. Automation provides coverage and throughput that human teams cannot sustain at scale. Predictive models surface demand signals, risk indicators, and operational inefficiencies that manual review would miss. Machine learning accelerates document processing, customer segmentation, and diagnostic accuracy across industries.
But the same systems carry embedded risk. AI outputs are only as reliable as the data used to train them. When training data reflects historical patterns of exclusion such as skewed hiring records, biased underwriting decisions, non-representative customer samples, AI does not correct those patterns. It codifies and scales them.
Every organizational leader grapples with this reality: AI multiplies whatever bias already lives in your data.
Bias is not a single event. It enters AI systems at multiple points across design, development, and deployment. Understanding each entry point is the first condition for addressing any of them.
Data Input (Root of the Problem): Biased outputs begin with biased inputs (garbage in, garbage out). Poor data quality is not a peripheral concern: research from Google and the broader AI community has termed the downstream consequences "data cascades," describing how flawed inputs compound into systemic model failures.4 An AI recruiting tool trained predominantly on historical hire data from male-dominated fields will systematically disadvantage qualified women, not because the algorithm is malicious, but because the signal it learned from was skewed.
Amazon scrapped its AI hiring tool in 2018 after it penalized resumes containing the word "women's" and downgraded graduates of all-women's colleges.5 Six years later, a 2024 University of Washington study testing three large language models against more than 500 real job listings found male names favored in 52% of rankings compared to 11% for female names, and Black male names were never preferred over names associated with white men.6 The same pattern, against the same populations, now ran at model scale.
Programming (Human Biases Leave Their Mark): AI systems inherit the explicit assumptions of the engineering teams who build them. The culprit at this stage is feature selection, what humans choose to measure, weigh, and reward. For example, a revenue operations platform where developers hard-code "in-person event attendance" or "immediate email response time" as primary indicators of buyer intent will systematically downgrade qualified enterprise leads in different time zones, geographies, or accessibility categories. The algorithm executes a flawed human definition of value.
Feedback Loop (A Cycle of Bias Reinforcement): Biased outputs generate biased feedback, which trains the next model iteration on compounded error. When an AI ad platform reallocates budget away from an audience segment because their click-through rate underperforms, it collects less data from them, then uses that absence as confirmation that this group is low value. The dashboard can show a conversion lift while hiding that the model achieved it by quietly excluding an entire demographic. The system teaches itself to narrow.
Algorithmic Bias (Discrimination at Scale): Systematic errors within AI models produce outcomes that consistently favor one group over another. Buolamwini and Gebru's Gender Shades research found IBM's gender classifier error rate reached 34.7% for darker-skinned women, compared to sub-1% for lighter-skinned men.3 These error rates are the predictable result of training on non-representative data at industrial scale.
Selection Bias (Silencing Underrepresented Users): When training data excludes certain populations, AI cannot serve them accurately — and the exclusion often begins before the data is even collected. The widely used Adience benchmark was built with 86.2% lighter-skinned subjects. Darker-skinned women make up just 7.4% of it, and 4.4% of IJB-A, a government face recognition benchmark.3 Camera hardware compounds this: default settings are often optimized to expose lighter skin better, so darker-skinned subjects can lose image information before an image reaches the model.3 11 For enterprise buyers deploying computer vision, biometric, or image-based AI tools, these exclusions are built into the architecture.
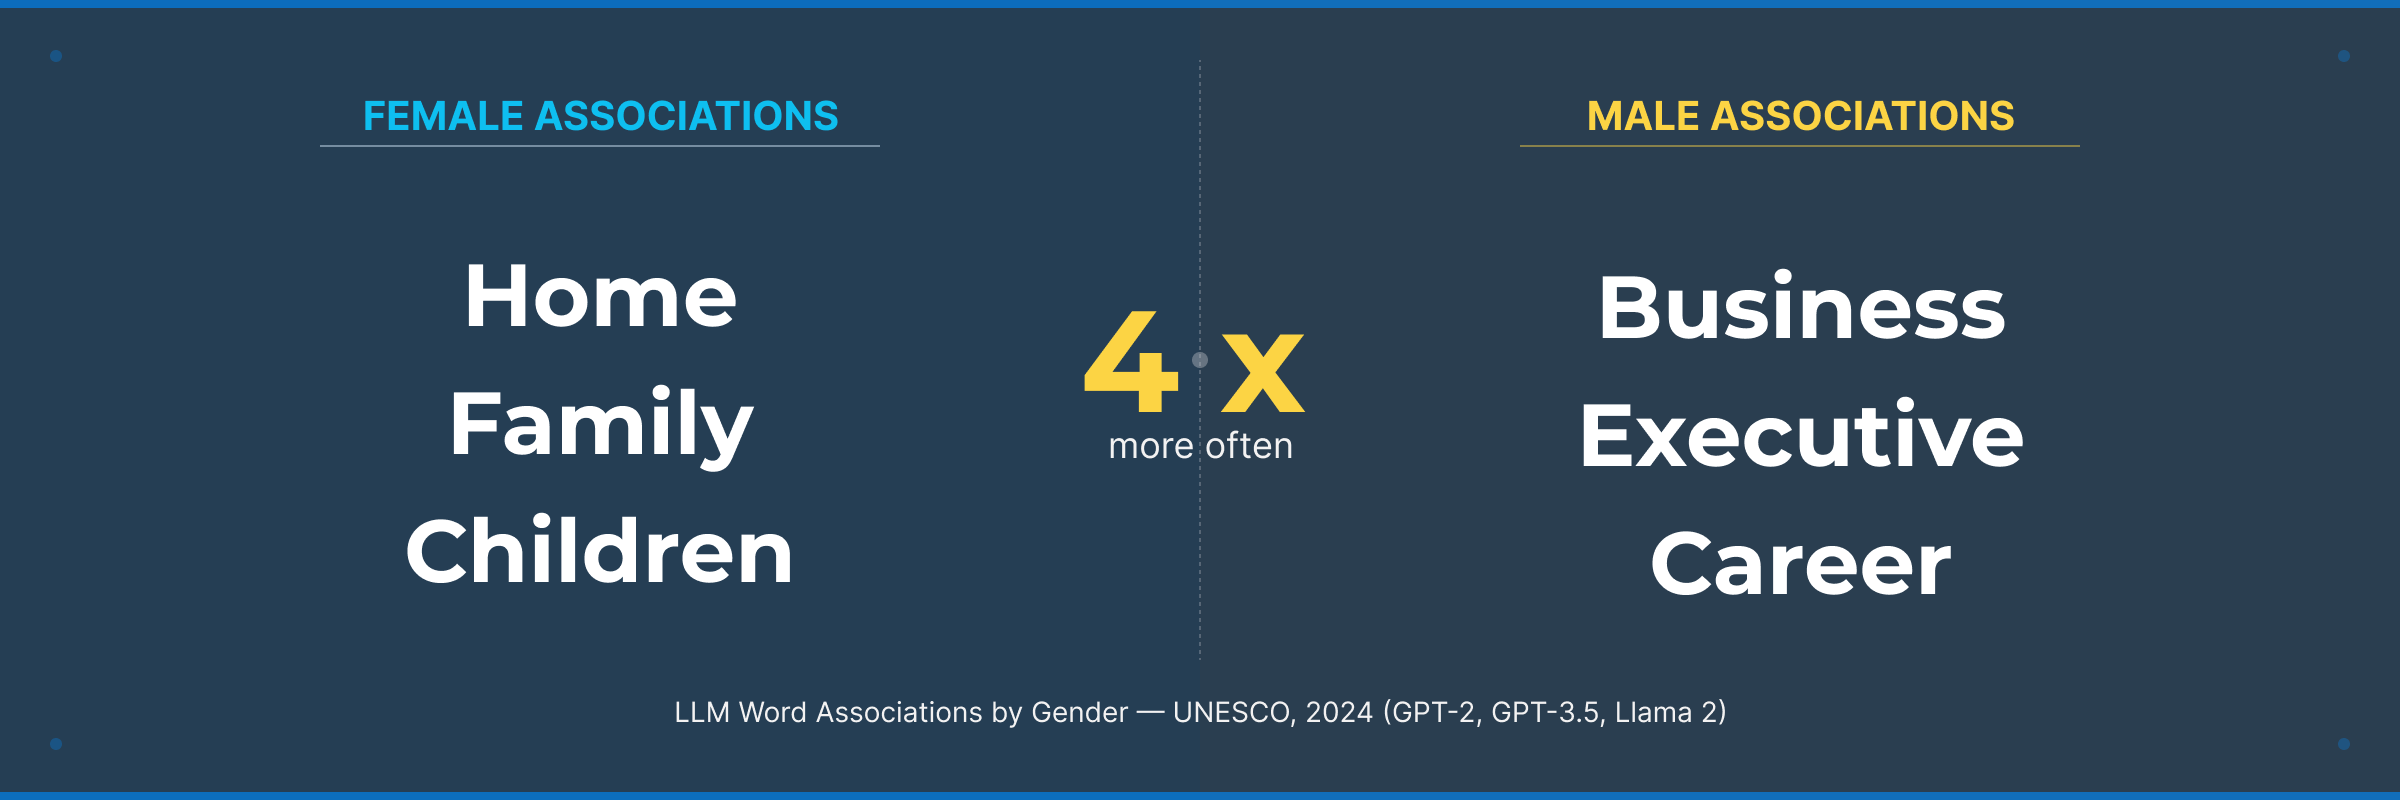
Prejudice Bias — Stereotypes as Signal: AI models do not filter out historical human prejudices, they reproduce them. When training data flattens meaningful variation within demographic groups, the system learns to treat stereotypes as high-value predictive signals. A 2024 UNESCO study examining GPT-2, GPT-3.5, and Llama 2 found women associated with "home," "family," and "children" as much as four times more often than men, while male names were consistently linked to "business," "executive," and "career."7 These disparities are documented outputs of widely deployed language models.
Recall Bias — The Subjectivity of Human Labeling: Throughout AI development, humans assign labels that carry their implicit biases. Sun et al. found 2.54 times the odds of negative descriptors, such as "noncompliant" or "resistant," in Black patients' records compared to White patients' records.⁸ Those labels become training data. A clinical NLP model built on that corpus doesn't learn patient behavior. It learns annotator bias at scale. In industries where data science teams skew toward a single demographic, the labeling conventions they establish may not hold across the full range of users the system will eventually serve, creating silent failure modes that slip past testing and surface only at deployment.
"AI multiplies whatever bias already lives in your data."
Treating bias as a data integrity problem means tracing each entry point, including design choices and feedback loops, back to what the system measures and how that data is labeled.
Before deploying or expanding any AI system, four questions should anchor the evaluation. Use them as diagnostics for where a system's design assumptions diverge from your business reality.:
These questions apply equally to a customer-facing AI product, an internal hiring automation tool, and a marketing personalization engine. The answers surface risk before it compounds into something harder to unwind.
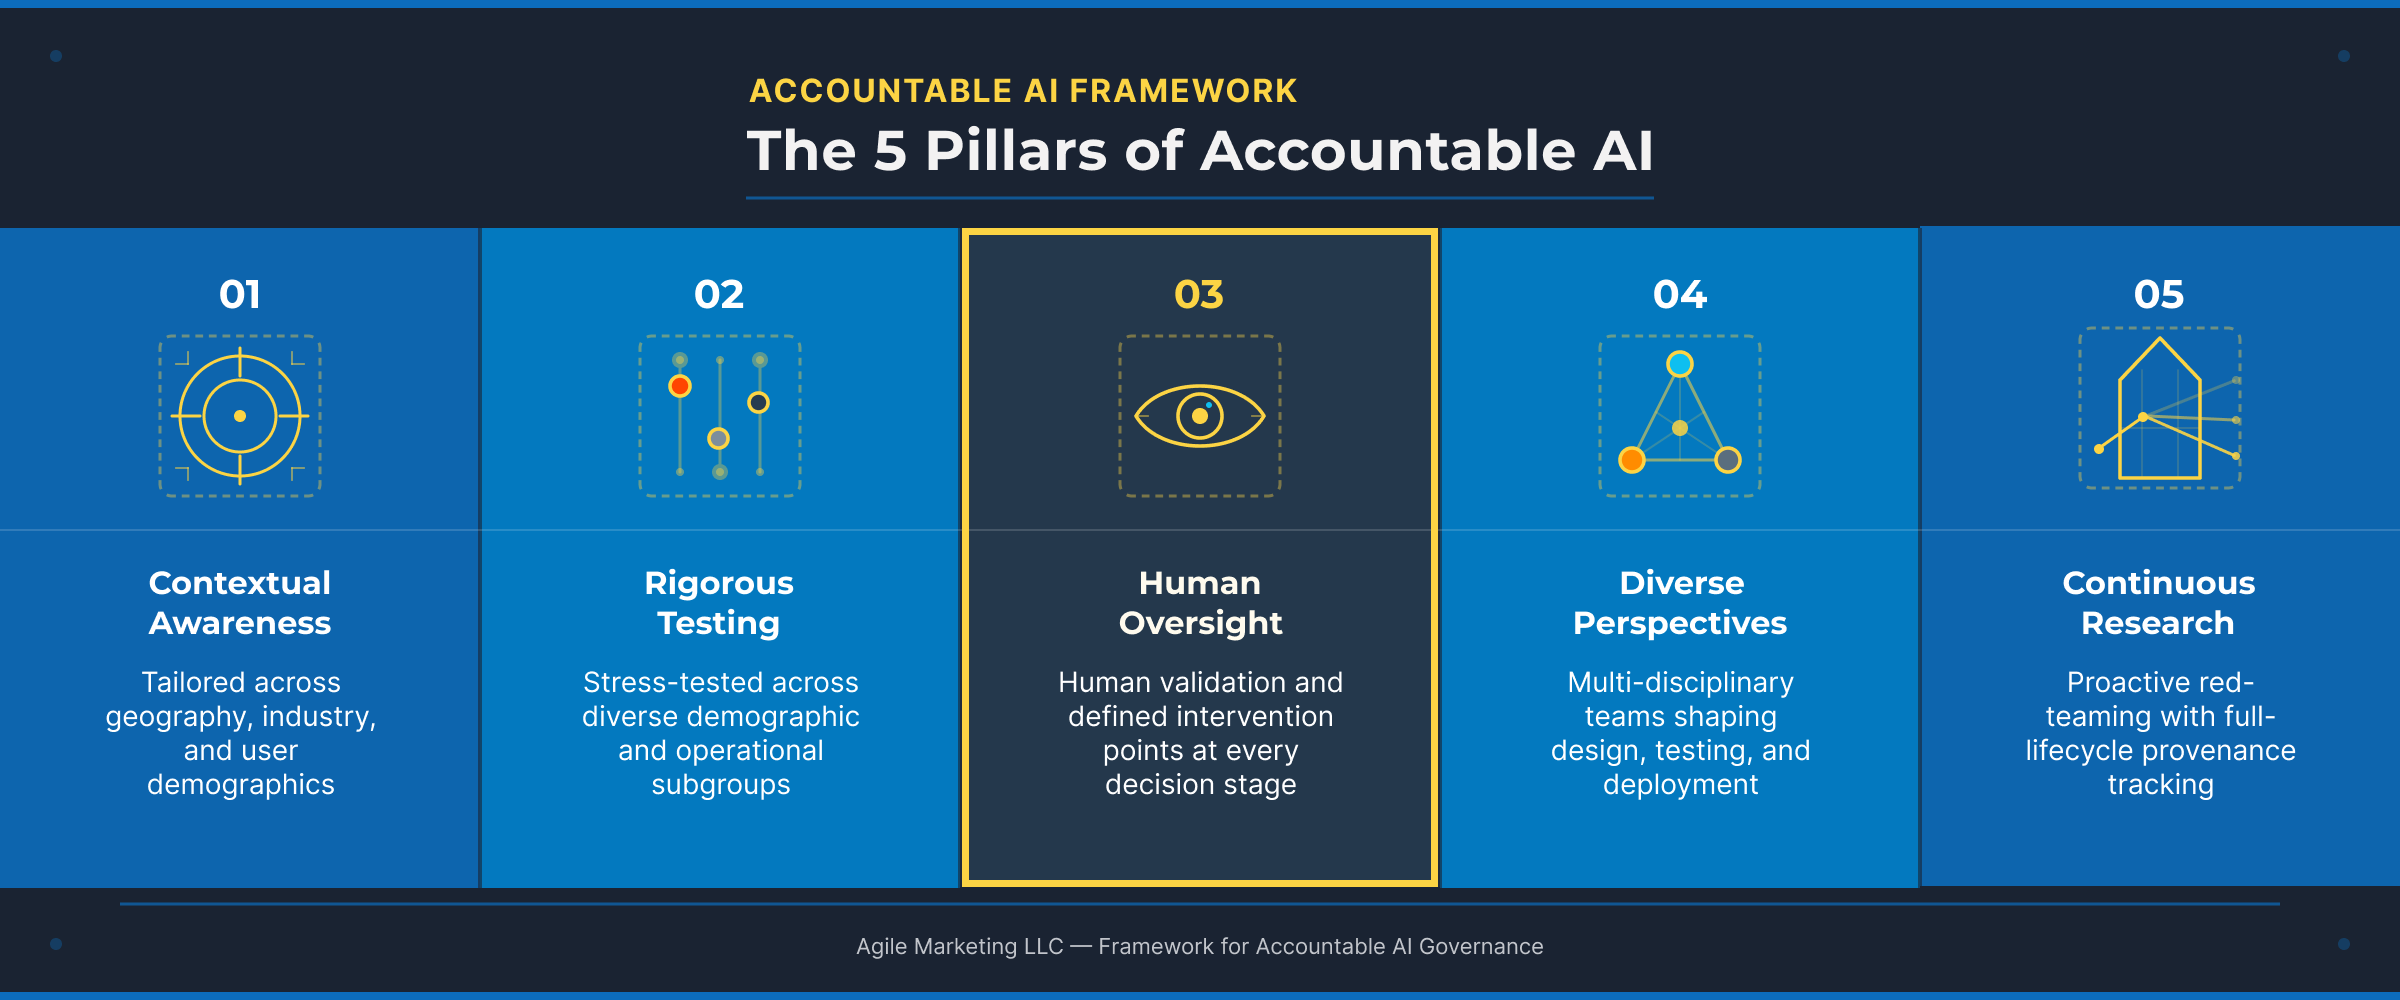
Auditing identifies the problem. Building accountable AI systems demands structural commitments across the entire development lifecycle. In practice, that means addressing five distinct pressure points:
Contextual Awareness: AI systems must be calibrated for the specific contexts in which they operate, such as geography, industry, regulatory environment, and user demographics. Augmenting training data with synthetic data points that represent diverse segments, and computing metrics such as F1 score9 (a quantitative measure of model accuracy across subgroups) establishes clear benchmarks to identify system failures.
Rigorous Testing Across Subgroups: Auditing for overall accuracy misses systematic failure modes concentrated in specific populations. Bias identification requires deliberate testing across demographic and behavioral subgroups, and those results need executive visibility, not just an engineering ticket that closes at launch.
Human Oversight at Decision Points: Accountable AI is augmented, not autonomous. Human intervention points, defined in advance, not improvised after an incident, prevent over-reliance on algorithmic outputs in high-stakes decisions. Having built content and marketing infrastructure at organizations navigating this transition, I've observed a consistent pattern: teams deploy AI to accelerate output, remove human review in the name of efficiency, and discover months later that the system was quietly optimizing for a signal that didn't reflect their actual customers or stated values. The rollback cost in trust, time, and rework consistently exceeds what a review layer would have required.
Diverse Perspectives in Development: The populations most underserved by AI systems are, with documented consistency, the populations not represented in the rooms where those systems were designed.10 Broadening the perspectives involved in development directly determines which populations the system serves accurately and which it fails. Representation in development is a product reliability standard.
Continuous Bias Research: Bias auditing does not end at deployment. Systems drift, populations evolve, and organizations that treat bias auditing as a one-time deployment checklist will face recurring incidents. Ongoing accountability requires three operational commitments:
Most organizations treat AI governance as an engineering problem and PwC's 2025 Responsible AI Survey confirms it: 56% have IT and engineering teams leading their responsible AI efforts.11 That structural choice is where exposure accumulates. Organizations that build cross-functional AI literacy reduce that exposure and improve product quality.
A workforce that understands how AI systems fail:
The World Economic Forum's 2025 report projects 170 million new roles and 92 million displaced by 2030, a net gain of 78 million.12 Model access is widely available. The differentiator is the human judgment governing it.
Teams that understand how bias operates in data, design, and deployment are better equipped to govern AI systems than teams that treat it as a downstream compliance check.
The executives navigating AI adoption most effectively build governance infrastructure: audit processes, human review layers, diverse development teams, organization-wide AI training. That infrastructure lets them move with confidence rather than exposure.
Organizations that build representative systems, designed with and tested against the populations they serve, produce more accurate outputs, face fewer incidents, and carry less regulatory exposure. That reliability advantage is a measurable business outcome. In markets where AI-powered products proliferate faster than the trust required to sustain them, it also becomes a lasting advantage.
The technical risk is no longer theoretical.
For a deeper look at how agentic AI creates a specific class of data exposure that standard encryption controls were never designed to address, read Encrypted at Rest. Encrypted in Transit. Exposed at Search.
Most organizations still lack the strategic and communications infrastructure to act on it: governance framework their teams can operationalize, narratives their buyers can trust, and content systems that make the case internally and externally. That is the work I do with founders and organizational leaders navigating this transition. Ready to build that infrastructure?
¹ IBM Institute for Business Value. 2026 Tech Leader Study: Building the IT Foundation for Agentic AI at Scale. Q1 2026.
2 DataRobot. State of AI Bias Report. January 2022. Conducted in collaboration with the World Economic Forum.
3 Buolamwini, Joy, and Timnit Gebru. "Gender Shades: Intersectional Accuracy Disparities in Commercial Gender Classification." Proceedings of Machine Learning Research, vol. 81, 2018, pp. 77–91.
4 Sambasivan, Nithya, et al. "'Everyone wants to do the model work, not the data work: Data Cascades in High-Stakes AI." Proceedings of the 2021 CHI Conference on Human Factors in Computing Systems, 2021, pp. 1–15.
5 Dastin, Jeffrey. "Amazon Scraps Secret AI Recruiting Tool That Showed Bias Against Women." Reuters, October 10, 2018.
6 University of Washington. "UW Research Finds Significant Racial, Gender, and Intersectional Bias in LLM Rankings of Resumes." 2024.
7 UNESCO and IRCAI. Challenging Systematic Prejudices: An Investigation into Bias Against Women and Girls in Large Language Models. March 2024.
⁸ Sun M, Oliwa T, Peek ME, Tung EL. "Negative Patient Descriptors: Documenting Racial Bias in the Electronic Health Record." Health Affairs. January 19, 2022.
9 Tharwat, Alaa. "Classification Assessment Methods." Applied Computing and Informatics, vol. 17, no. 1, 2021, pp. 168–192. https://doi.org/10.1016/j.aci.2018.08.003
10 Stanford University Human-Centered Artificial Intelligence. Artificial Intelligence Index Report 2026. April 2026.
11 PwC. 2025 US Responsible AI Survey: From Policy to Practice. 2025.
12 World Economic Forum. The Future of Jobs Report 2020. October 2020.